
Pinecone
SoftwareA managed vector database that powers AI search, recommendations, and retrieval for modern AI applications.
About Pinecone
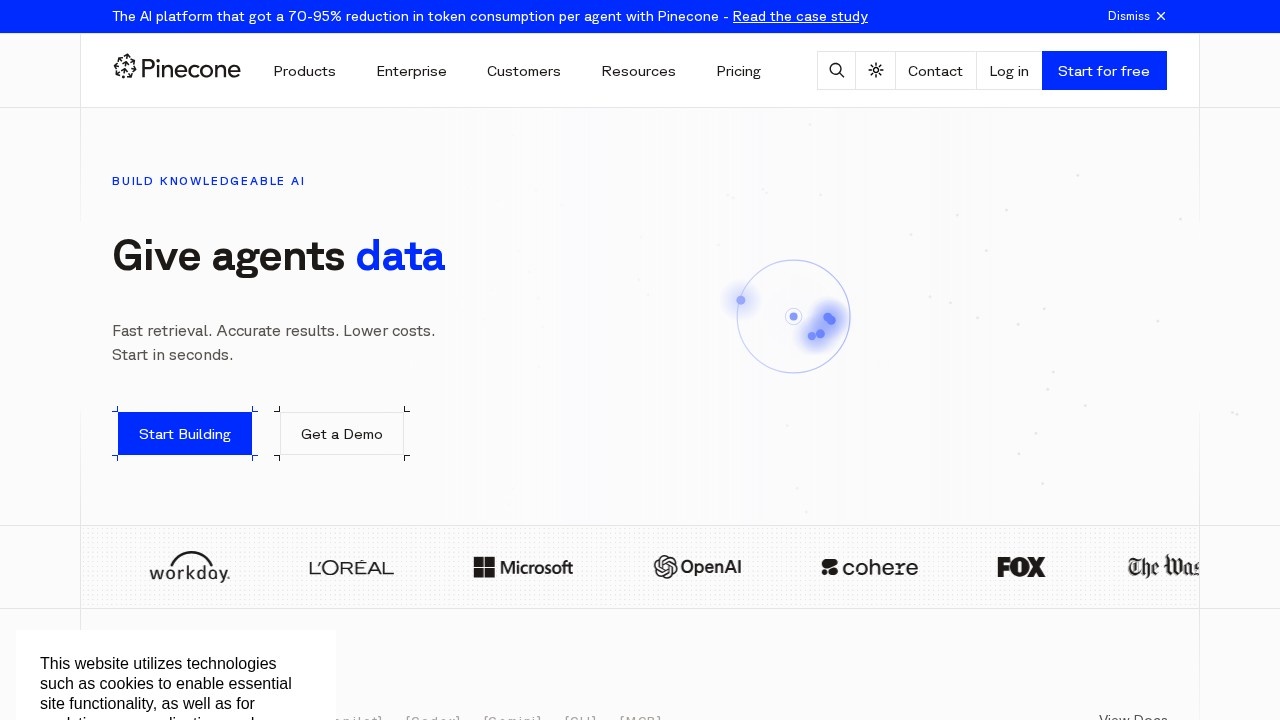
Pinecone is a fully managed vector database built to power AI applications with fast, accurate retrieval at scale. When an AI app needs to find the most relevant information — documents for a RAG system, similar items for recommendations, matches for search — Pinecone is the purpose-built infrastructure that makes that reliable in production, without teams having to build and run a vector store themselves.
What Pinecone is
Pinecone stores vector embeddings and searches them for similarity extremely quickly, using Rust implementations of algorithms from published research to keep latency low. It's serverless and fully managed — separating storage from compute, auto-scaling, and indexing updates so they're searchable in seconds — and it supports hybrid search, metadata filtering and built-in reranking to make results genuinely relevant.
Who it's for
Pinecone serves developers and enterprises building AI agents, search systems and recommendation engines — over 10,000 customers across many industries. It's for teams that need production-grade vector search at scale and would rather use managed infrastructure with real SLAs than operate their own vector database.
What it offers
- Fast vector similarity search (Rust-based, low latency)
- Hybrid search combining vector, keyword and full-text methods
- Metadata filtering and namespace-based multi-tenancy
- Sparse and dense embeddings with built-in reranking
- Serverless architecture separating storage from compute
- Scales to billions of vectors and 1000+ queries per second
- Updates indexed and searchable in seconds
- SDKs, intuitive APIs and MCP integration for AI agents
Purpose-built, not bolted on
Pinecone's defining strength is that it's a purpose-built vector database, not vector features added onto a general-purpose system. That focus shows up in performance — low-latency search backed by a research team publishing peer-reviewed retrieval algorithms — and in reliability at scale. For production AI where retrieval speed and accuracy directly shape the user experience, using infrastructure designed from the ground up for vectors is a meaningful advantage over a retrofitted database.
Serverless scale without the ops
Pinecone's serverless architecture separates storage from compute and auto-scales hands-free, so it handles everything from a small prototype to billions of vectors and 1000+ queries per second without teams managing servers. Object-storage-based tiering keeps costs efficient, and updates are searchable within seconds for dynamic workloads. That means developers focus on their application, not on capacity planning or keeping a database cluster healthy — the infrastructure burden is Pinecone's, not theirs.
Relevance that holds up in production
Good retrieval is about relevance, not just speed, and Pinecone provides the tools for it: hybrid search that blends vector similarity with keyword and full-text matching, metadata filtering to constrain results, and built-in reranking models to order them well. Namespace-based multi-tenancy (up to 1M namespaces on Enterprise) lets SaaS companies cleanly isolate each customer's data. Together these turn raw similarity into accurate, well-filtered answers suitable for real applications.
Ready for real production demands
Pinecone is built for the realities of running AI in production, not just prototypes. It offers production-grade SLAs, compliance options and even bring-your-own-cloud (BYOC) deployment for organizations with strict requirements, plus consumption-based pricing where you only pay for the operations you actually perform. Namespace multi-tenancy keeps each customer's data isolated for SaaS use cases. For teams putting AI features in front of real users, that combination of reliability guarantees, security options and efficient pricing is what turns a promising demo into something they can safely depend on at scale.
Why choose Pinecone
For developers and enterprises building production AI that depends on fast, accurate retrieval — RAG, agents, search, recommendations — Pinecone is a leading managed vector database. Its purpose-built, research-backed performance, serverless scale, hybrid search and reranking, multi-tenancy and consumption-based pricing make it a practical way to add reliable vector search to AI applications, without the burden of building and operating that infrastructure yourself.
Tags
Ratings & reviews
No ratings yet
Be the first to rate Pinecone — your honest take helps others decide.
- No reviews yet — be the first to rate Pinecone.
Similar softwares
ConvertAny
Free online file, unit, text, app icon and developer conversion tools. No signup required.
UsageAtlas
Free open-source AI usage tracker for coding tools.
热核算力 (CodexHot)
Paid OpenAI-compatible GPT API access for developers, with prepaid usage from CNY 5.
Compare Pinecone
Similar software
LaunchNest LN
LaunchNest LN is a product launch platform for SaaS, AI tools, and developer products. Discover new products, launch your own, and grow with a global community.
Weaviate
An open-source AI-native vector database for search, RAG and agentic applications at scale.
Chroma
Open-source search infrastructure for AI — vector, full-text and metadata search in one serverless database.
Qdrant
A high-performance, open-source vector database in Rust for AI search, RAG and recommendations.

Exa
A search engine and API built for AI — find exactly the web content you mean using meaning, not just keywords.
Cohere
Enterprise-focused large language models and AI infrastructure for building secure, private generative AI applications.
Related reads

Text Differ: A Simple and Powerful Online Text Comparison Tool
Compare two versions of text, code, or documents instantly with Text Differ. Discover its key features, comparison modes, and practical uses.
The 6 Best Vector Databases in 2026 (for RAG & AI Search)
Vector databases power RAG, semantic search and AI memory. Here are the six best in 2026 — from managed Pinecone to open-source Qdrant, Weaviate and Chroma — with who each is for.
The 5 Best Open-Source Authentication Tools in 2026
Open-source auth lets you own your users' data and avoid per-user pricing. Here are the five best self-hostable authentication tools in 2026, compared.
Community discussion (0)
Ask questions, share tips, or compare notes with other Pinecone users.